| ARC-AGI-2 (Abstract Fluid Reasoning) |
100.0% (Multi-Step Reasoning) |
~38%–54% (Standard Low-Compute) |
85.0% Human Panel |
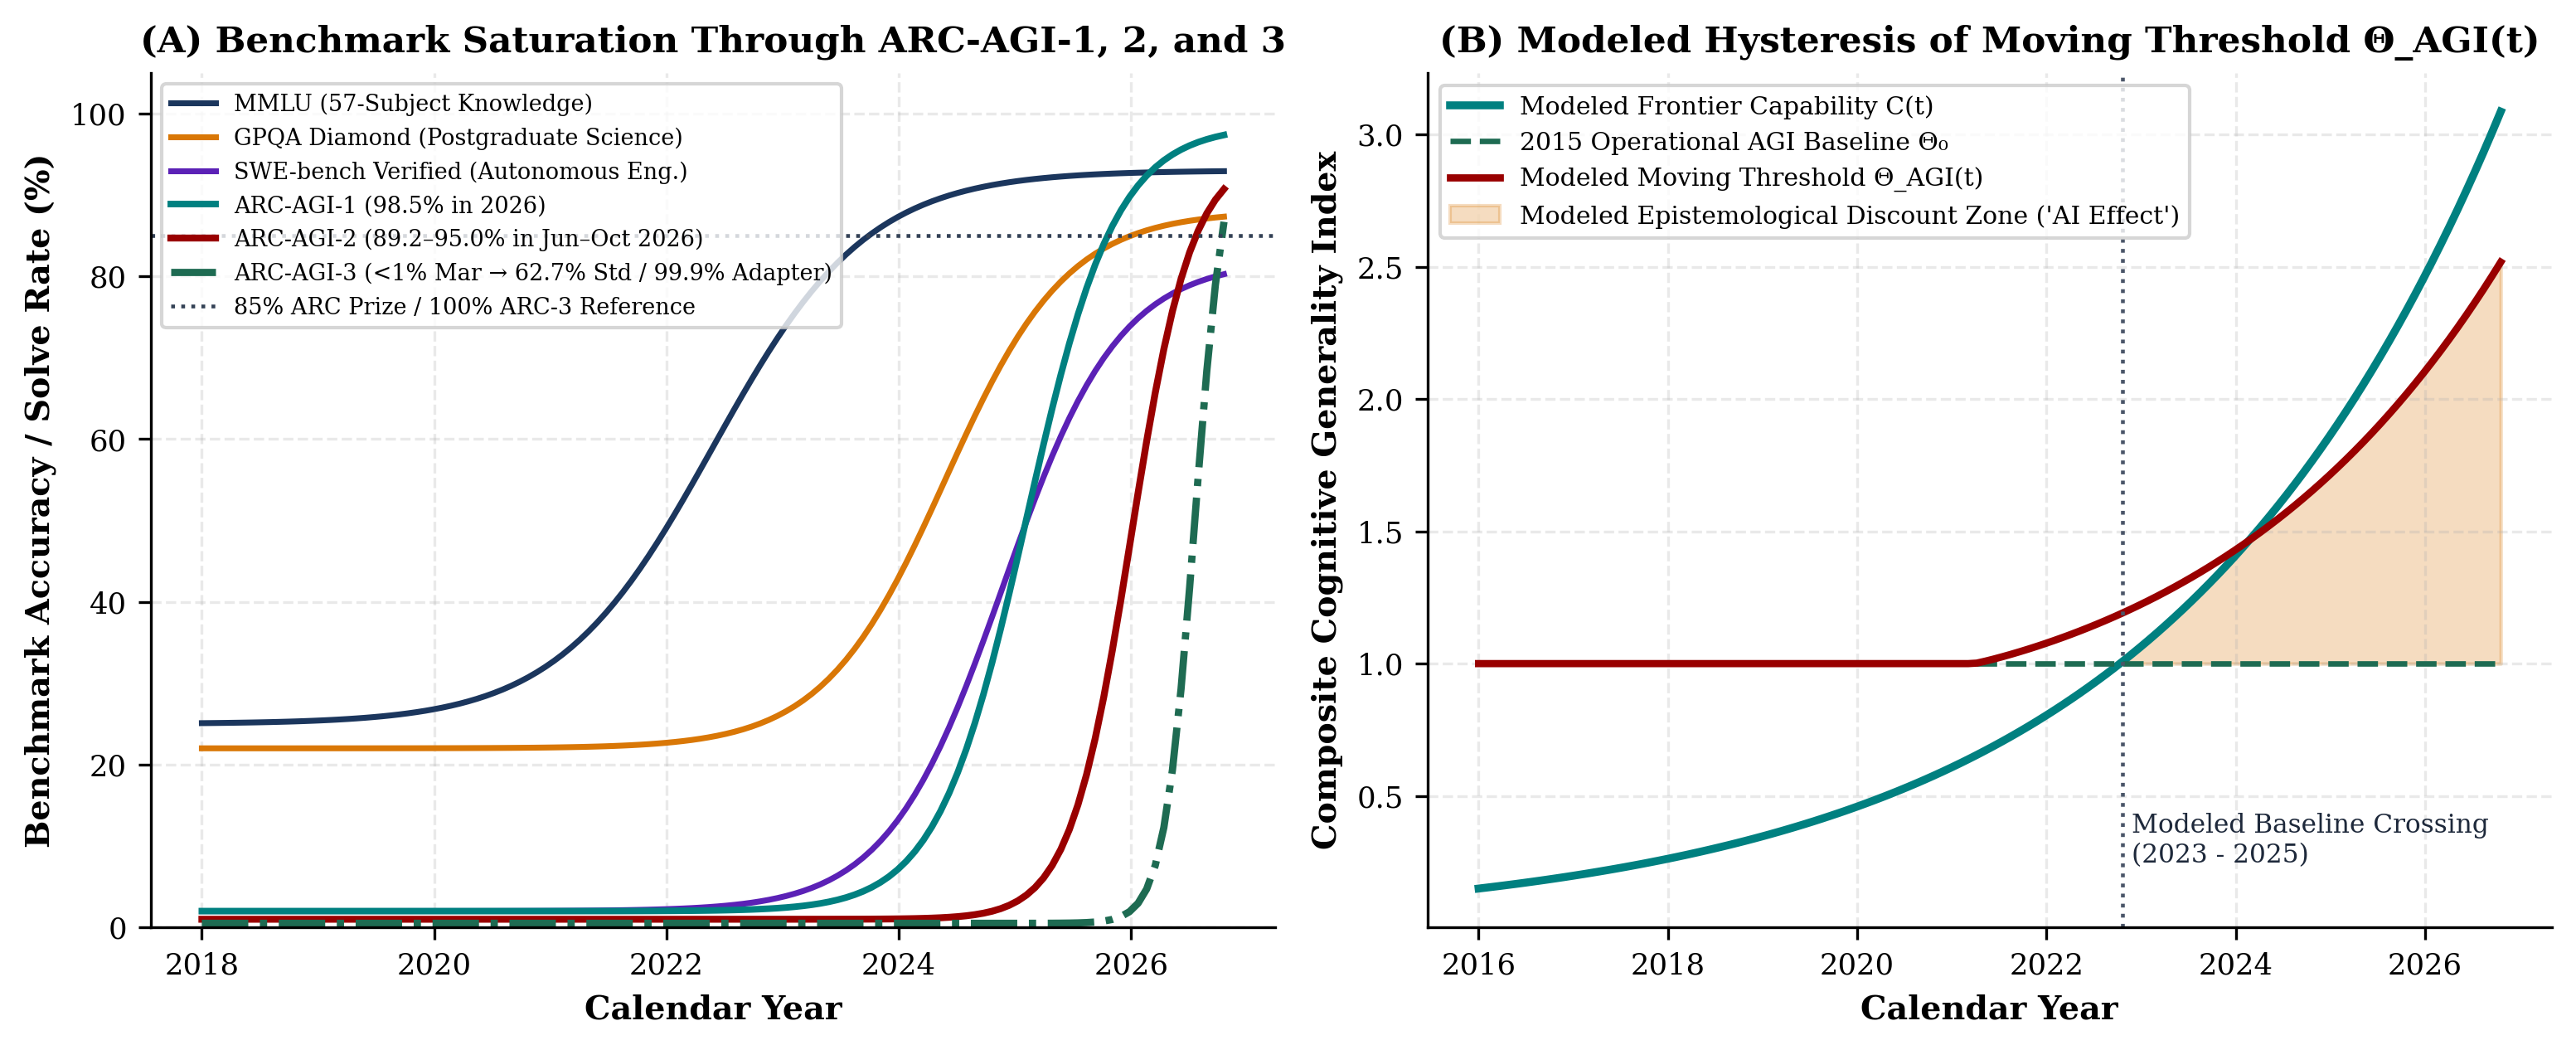
Shatters static fluid-intelligence ceiling; triggers transition to interactive ARC-AGI-3 |
| ARC-AGI-3 (Interactive Novel Environments) |
62.6% (GPT-6 Astra; reported evaluation cost: $18,817 high / $26,098 max reasoning) |
0.26% (Standard Zero-Scaffold Harness) |
~85.0% Human Reference |
Demonstrates 240× evaluation-setup / harness sensitivity (modeled separately from ηgate in §3.3) |
| GPQA Diamond (PhD-Level Physics, Chemistry, Biology) |
94.4% (Frontier Pro / Thinking) |
~71%–79% (Consumer Default) |
69.7% Domain PhDs |
Exceeds human PhD domain specialists by +24.7 percentage points |
| SWE-bench Verified (Autonomous Software Engineering) |
91.0% (Agentic Scaffold) |
~52%–64% (Single-Turn Chat) |
~75.0% Senior Engineer |
High benchmark solve rate contrasts with −19% external developer RCT slowdown [125] |
| FrontierMath (Research-Grade Mathematics) |
56.4% (High-Compute Search) |
<15% (Standard Pass@1) |
Fields/IMO Medalist Bar |
Rapid jump from <2% (2024) to 56.4% (2026) under test-time compute scaling |
| Humanity’s Last Exam (HLE) (1,000+ Expert Consortium) |
58.7% (Frontier Ensemble) |
~24%–32% (Default API) |
Expert Consortium Ceiling |
Crosses majority threshold on benchmark explicitly designed as final static test |
| METR Autonomous Task Horizon (Long-Horizon Agency) |
T50 ≈ 14.5 Hours (50% Success) |
T80 < 2.0 Hours (80% Reliability) |
Multi-Day Human Project |
7× gap between 50% demo horizon and 80% production reliability drives ηabsorb = 0.720 |